

Machine Anomalies vs. Machine Failures: Why the Difference Matters
Anomaly, fault and failure are different things. The four jobs of machine health analysis, and one synthetic example followed from first sign to remaining life.
Company announcements, product notes, research and perspectives on intelligence for the physical world.
Anomaly, fault and failure are different things. The four jobs of machine health analysis, and one synthetic example followed from first sign to remaining life.

One pump failure followed from bearing to aftermath: where the costs hide, a worked estimate line by line, and why standby condition is the real risk.

How a data center cooling plant works, how its pumps, chillers, towers and CDUs fail, which signals reveal those faults, and where prediction pays most.

AI data centers run on pumps, chillers, transformers and switchgear. At 120 kW per rack, the physical plant needs the condition monitoring factories use.

Power and cooling cause two thirds of serious data center outages, and AI racks draw about 15 times a typical rack's power. The plant needs closer watching.

The product philosophy behind NODE: design intent shaped by heat, dust, vibration and busy installers, one family in three sizes, and honest concept renders.
Preventive and predictive maintenance compared: how each works, what DOE figures say about cost, why most parts have no wear-out age, and how to choose.
Remote and critical sites lose connectivity. Local inference keeps detection running through outages, cuts latency and bandwidth, and fits OT security.
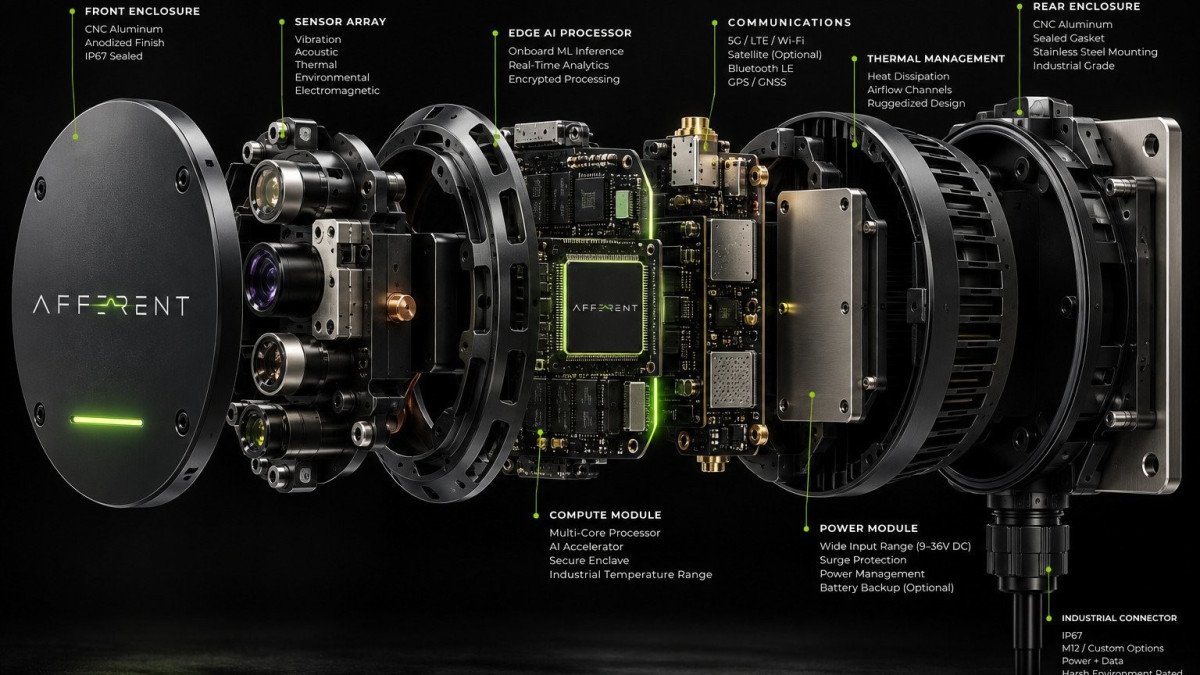
The proposed architecture of NODE, function by function: sensing, signal conditioning, edge compute, buffering, secure links and the reasons for each.